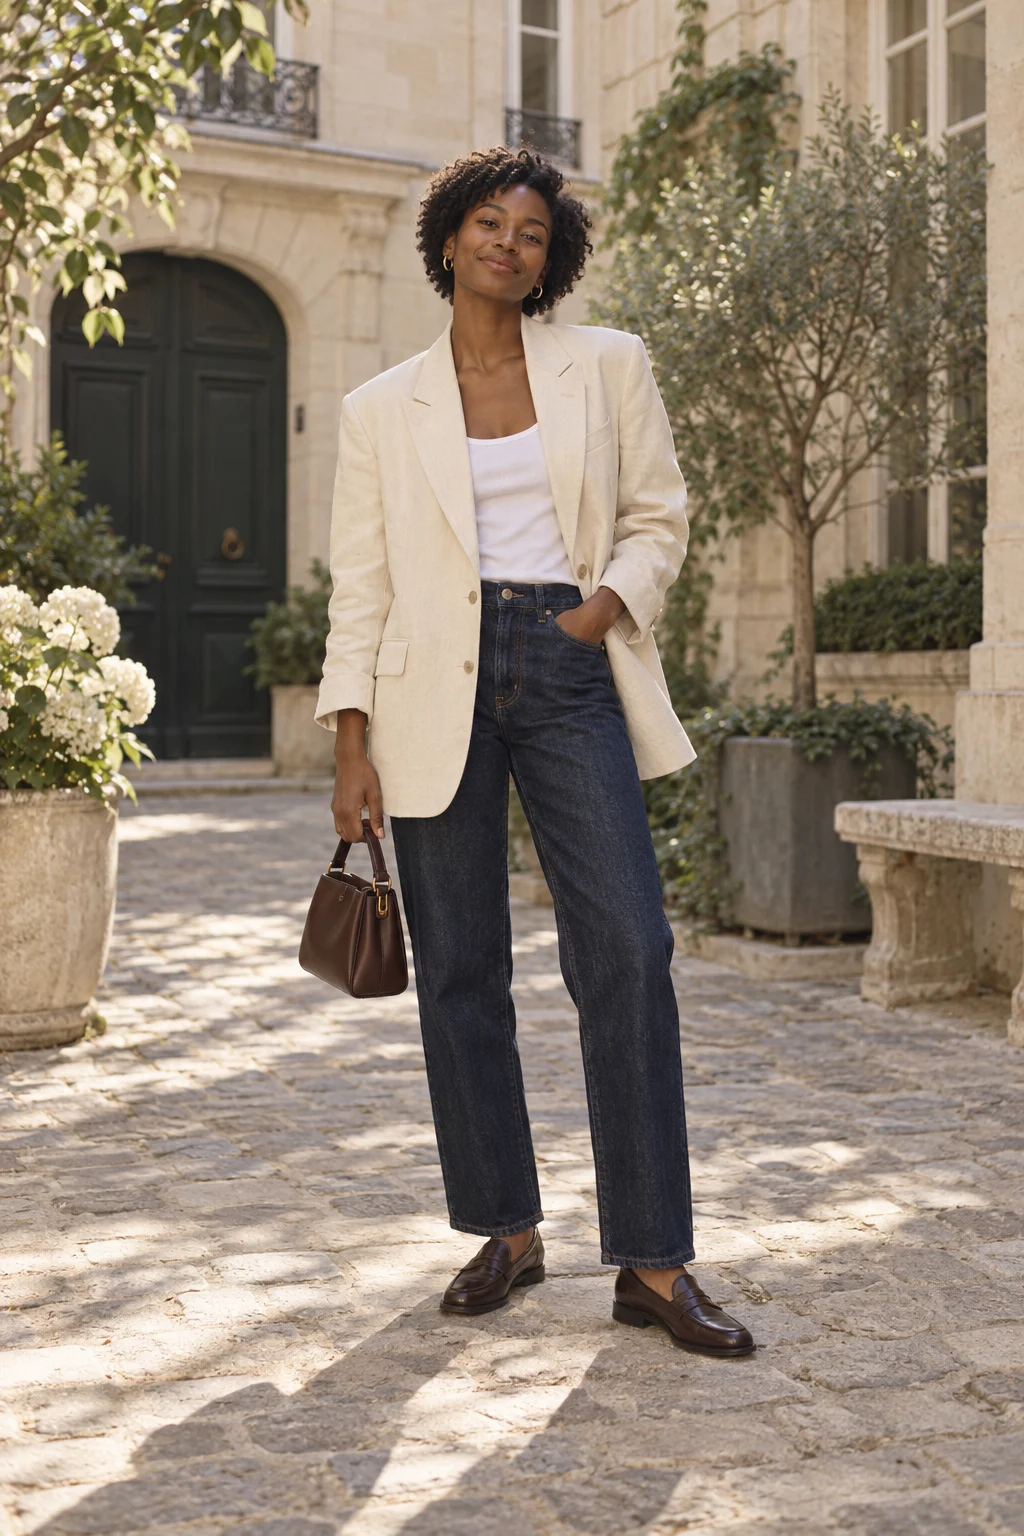
“The blazer works. Keep the darker denim—it gives the look structure.”
One continuous loop
PerceptionFresh camera frames01
UnderstandingVisual + conversational context02
GuidanceThe right words, in the moment03
Your prompts. Your models. Your tools.
Built for the physical world.
Hosted APISelf-hosted SDKAny specialty
Perception is a loop, not a prompt.
From seeing the world to being useful in it.
Video, voice and reasoning, working together. So your agent can stay with the task as it changes.
ENGINE / 01
The latest frame. The relevant detail.
Video frames → image preparation → current visual context
Capture
8 fps
Process
4 fps
Stale frames
Discarded
camera.capture_fps8
Reported prototype benchmarks
Built to keep up.
9.8×
faster responsesvs GPT-6 Luna
Relative response time · shorter is better
GPT-6 Luna
Second Pair
8×
higher frame processing ratevs Gemini Live Video
Relative frames processed · longer is better
Second Pair
Gemini Live Video
>2.5×
cheaper per minutevs GPT-Live Voice
Relative cost per minute · shorter is better
GPT-Live Voice
Second Pair (at most)
Figures from our internal prototype, reported in the Second Pair pitch deck. Workload and model dependent; not independent benchmarks or performance guarantees.
One engine. Any specialty.
Your expertise. A whole new interface.
Cook, Handy and Coach are not separate products. Each is a configuration: a prompt, a set of tools and a proactivity policy on the same engine. Yours can be anything a camera can help with.
Another pair of eyes in the kitchen.
Watches
Pan, heat, colour, texture, what is already chopped.
Might say
“Turn the heat down a notch — the butter is starting to brown at the edges.”
The configuration that makes it
prompt
“You are a helpful cooking companion. Ask what the user is making. Give concrete next steps based on what is visible, and ask when the image is unclear.”
tools
lookup_ingredientcurrent_recipe_stepyour application’s own functions
proactivity
On — speaks up before something burns
Built for developers
Your stack. Your agent.
Choose separate speech, vision and reasoning models, set reasoning effort, decide how many frames are captured and analysed, register your own tools and set how proactive the agent may be. Run it through the hosted API or inside your own service.
from secondpair import (
AgentConfig, CameraConfig, ModelConfig, Models, PerceptionConfig, ProactivityConfig,
)
from secondpair.client importSecondPairClientconfig = AgentConfig(
name="Cook AI",
prompt="Help the user cook. Ask what they are making; give concrete next steps.",
models=Models(
speech=ModelConfig(name="openai:gpt-realtime"),
perception=ModelConfig(name="provider:vision-model"),
reasoning=ModelConfig(name="provider:reasoning-model", reasoning="high"),
),
camera=CameraConfig(capture_fps=8, processing_fps=4),
perception=PerceptionConfig(enabled=True, analysis_fps=0.5),
proactivity=ProactivityConfig(enabled=True, min_confidence=0.85),
)
# Inside your authenticated backend route. Keys stay in server secrets.asyncwithSecondPairClient(base_url=SECONDPAIR_API_URL, api_key=SECONDPAIR_API_KEY) as sdk:
credentials = await sdk.create_session(user_id=user.id, config=config)
SDK v0.1 — Python engine, TypeScript client and React binding. Packages are shared with early-access teams; they are not on a public registry, so don’t install similarly named packages. Model names above are placeholders for deployments you have access to.
Build with Second Pair
Build what comes next.
We’re onboarding a small number of teams building live, camera-first experiences. Tell us what you want to build; we’ll reply personally.